Warned in time, people manually checked more when the drone failed
With a simulated drone that failed more often, people given a verbal warning manually checked 63% of the time; without a warning, 22%.
The key idea
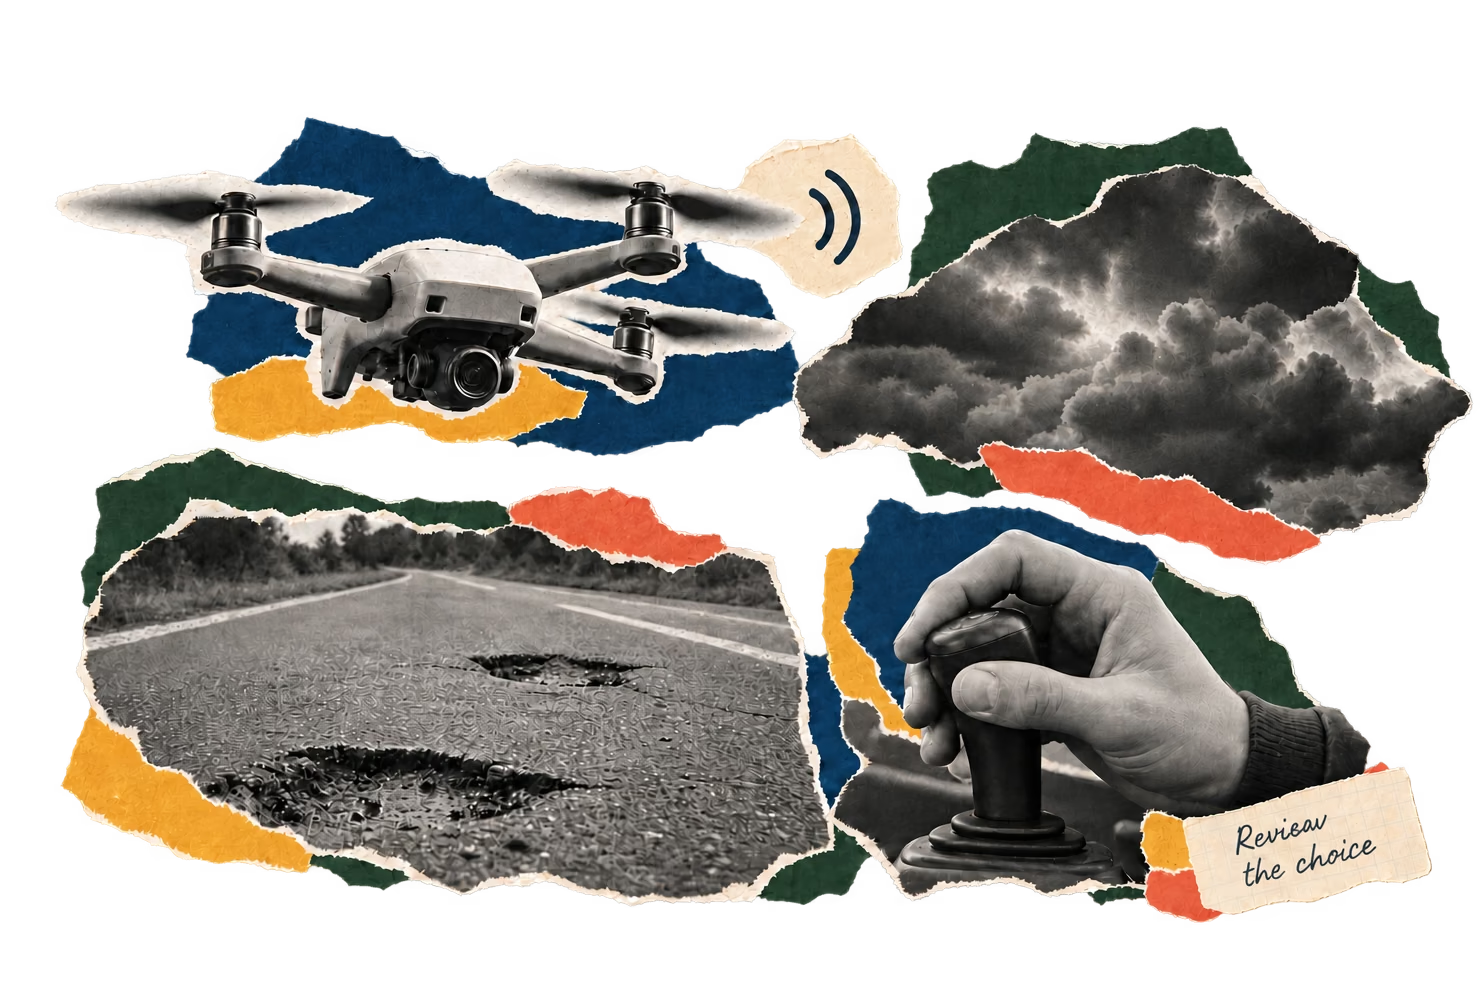
In the simulation, a timely warning led the group to choose manual review much more often when the system worsened.
The study, in plain language
Participants operated a simulated drone: they could review images themselves or delegate pothole detection. Initially, the system was highly accurate. Then a simulated storm reduced its reliability, and a visible indicator showed the change.
Among those who completed enough checkpoints, the verbal-warning group switched to manual review much more often than the no-warning group. On one measure, they also better distinguished potholes from normal areas. Overall accuracy did not show the same pattern: there was no difference among the five groups, although the verbal-warning group had the highest average. What changed was when people took control again.
What they found
- When the system worsened, the verbal-warning group chose manual review much more often.
- That group also better distinguished potholes from normal areas on one measure.
- The proportion of correct responses showed no clear differences among the five groups.
How they studied it
Participants were assigned to five groups. Researchers simulated a drone whose reliability declined during the task, from 90% to 50%. They compared how often participants took manual control and how they detected potholes, with adapted warnings or without them.
What the study cannot show
- Evidence comes from a brief simulation and participants who completed the route. Overconfidence was assessed; the same effect was not tested in real driving or across all tasks.
Something to think about
If you use an automated system, ask whether its warnings arrive just when you decide to delegate. This design reflection comes from a brief simulation.
The original study
Adaptive trust calibration for human-AI collaboration
Source under CC BY 4.0. English adaptation and explanation by PaperFlow, with AI assistance. The text has been reorganized for a general audience; it is not the complete paper and does not imply endorsement by its authors.
One study alone does not represent a field's consensus. Educational content does not replace professional advice. Report a possible error.